Best Server Monitoring Tools in 2026: By Stack
Compare server monitoring tools for cloud, Kubernetes, on-prem, network devices, real-time metrics, pricing, and operational ownership.
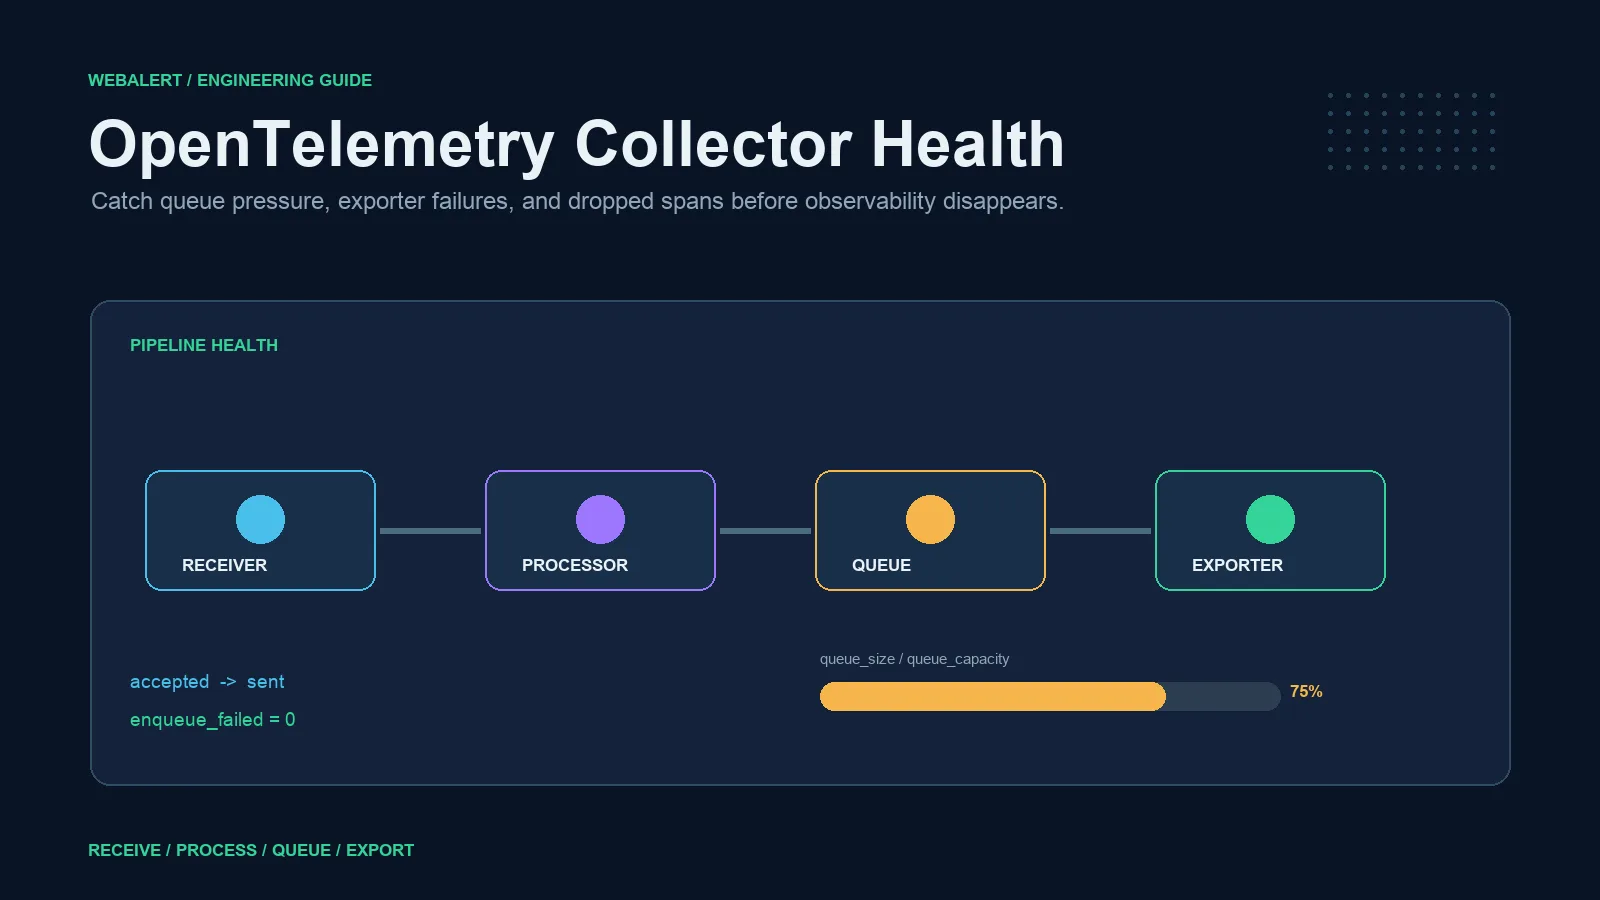
OpenTelemetry Collector Monitoring: Queues and Drops
Monitor Collector receive, refuse, enqueue, export and drop paths with queue utilization, exporter failures, memory pressure and end-to-end canaries.
Best APM Tools 2026: Architecture and Price
APM compared by pricing model, OpenTelemetry, enterprise automation, and high-cardinality analysis — Datadog, New Relic, Dynatrace (Aug 2026).
Best Log Monitoring Tools 2026: Ingest Cost Table
Log tools compared by ingest, indexing, retention, and who operates the cluster — Datadog, New Relic, Loki, Elastic, Splunk (Aug 2026).
Best Error Tracking Tools in 2026: By Workflow
Compare error tracking tools by free tier, event pricing, release health, mobile fit, replay, observability breadth, and uptime blind spots.
Prometheus Monitoring: Strengths, Gaps, and Setup
Understand Prometheus metrics, labels, PromQL and alerting, plus its outside-in, event-detail and pipeline blind spots and how to cover them.
Error Monitoring vs Uptime Monitoring: Differences
Compare exception tracking with outside-in uptime checks, see which failures each misses, and combine both without duplicating noisy alerts.
Log Monitoring: What Logs Catch, Miss, and Alert On
Build structured log monitoring with stable fields, rate-based alerts, correlation IDs and pipeline health while covering outages logs cannot observe.
What Is APM? Application Performance Monitoring Guide
Learn how APM uses traces, spans, service maps, errors and latency to diagnose application performance, and how it differs from uptime monitoring.
Active vs Passive Monitoring: Differences and Examples
Compare active synthetic checks with passive production telemetry, understand each method’s blind spots, and build a practical monitoring strategy using both.
Anomaly Detection in Monitoring: Move Beyond Static Thresholds
Compare anomaly detection with static thresholds, choose useful baselines, handle seasonality and cold starts, and turn outliers into actionable alerts.
Black-Box vs White-Box Monitoring: Key Differences
Compare outside-in black-box checks with internal white-box telemetry, understand their blind spots, and combine both for faster detection and diagnosis.
Four Golden Signals: Latency, Traffic, Errors, Saturation
Apply latency, traffic, errors and saturation to service monitoring, choose useful measurements, and alert on user impact instead of dashboard noise.
RED vs USE Method: Metrics, Differences, Examples
Use RED for service requests and USE for resources, understand each framework’s metrics and blind spots, and connect them during incident diagnosis.
P50 vs P95 vs P99 Latency Explained (With Practical Formulas & Tail Latency Examples)
Understand P50 (median), P95, and P99 tail latency. Learn why average latency is misleading, how percentiles are calculated, and how to set accurate SLO alerts.
OpenTelemetry Monitoring: Traces, Metrics, Logs
Instrument and operate OpenTelemetry traces, metrics and logs with semantic conventions, Collector pipelines, sampling, cardinality control and health checks.
Observability vs Monitoring: Differences and Examples
Monitoring detects defined conditions; observability supports investigation with telemetry. Learn their overlap, differences, and a practical adoption path.
Datadog Alternative for Focused Uptime Monitoring
Need a Datadog alternative for uptime checks? Compare synthetic pricing, observability depth, migration, and the limits of a focused tool.