Graceful Shutdown in Kubernetes: SIGTERM, Drain, and Deadlines
Implement graceful shutdown with readiness removal, SIGTERM handling, request and queue drain, resource cleanup, and Kubernetes termination deadlines.
Kubernetes ImagePullBackOff and ErrImagePull: How to Fix
What ImagePullBackOff and ErrImagePull mean, why Kubernetes can't pull your container image, and how to diagnose and fix the most common causes.
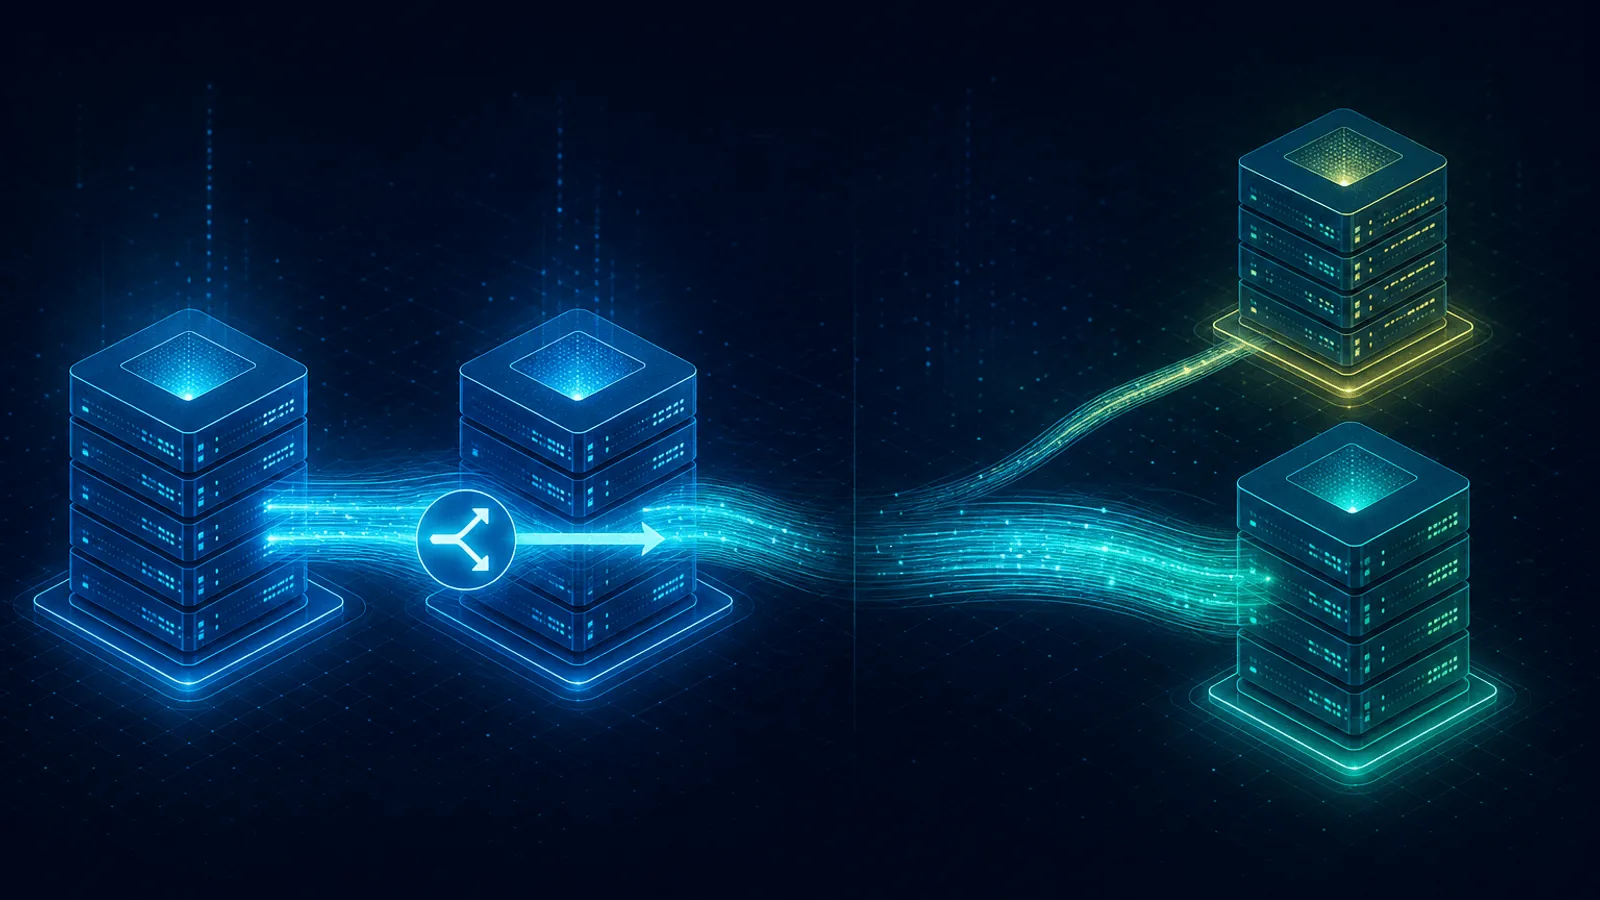
Blue-Green vs Canary Deployment: Differences, Rolling Updates, and How to Choose
Blue-green vs canary deployment: how each shifts traffic, rolls back, and handles the database, how rolling updates compare, and a guide to choosing.
Docker Container Unhealthy: How to Debug Health Checks
Why a Docker container shows 'unhealthy', how to read HEALTHCHECK logs, debug docker-compose health checks, and fix the most common causes fast.
DORA Metrics Explained: Four Keys, Five Metrics, and How to Measure Them
What DORA metrics are, why there are now five instead of four, and how to measure change fail rate, lead time and the rest, with formulas and worked examples.
Health Check Endpoint Design: /healthz vs /livez vs /readyz
Design reliable /healthz, /livez, and /readyz endpoints. Learn liveness vs readiness, Kubernetes probes, dependency checks, and alerting.
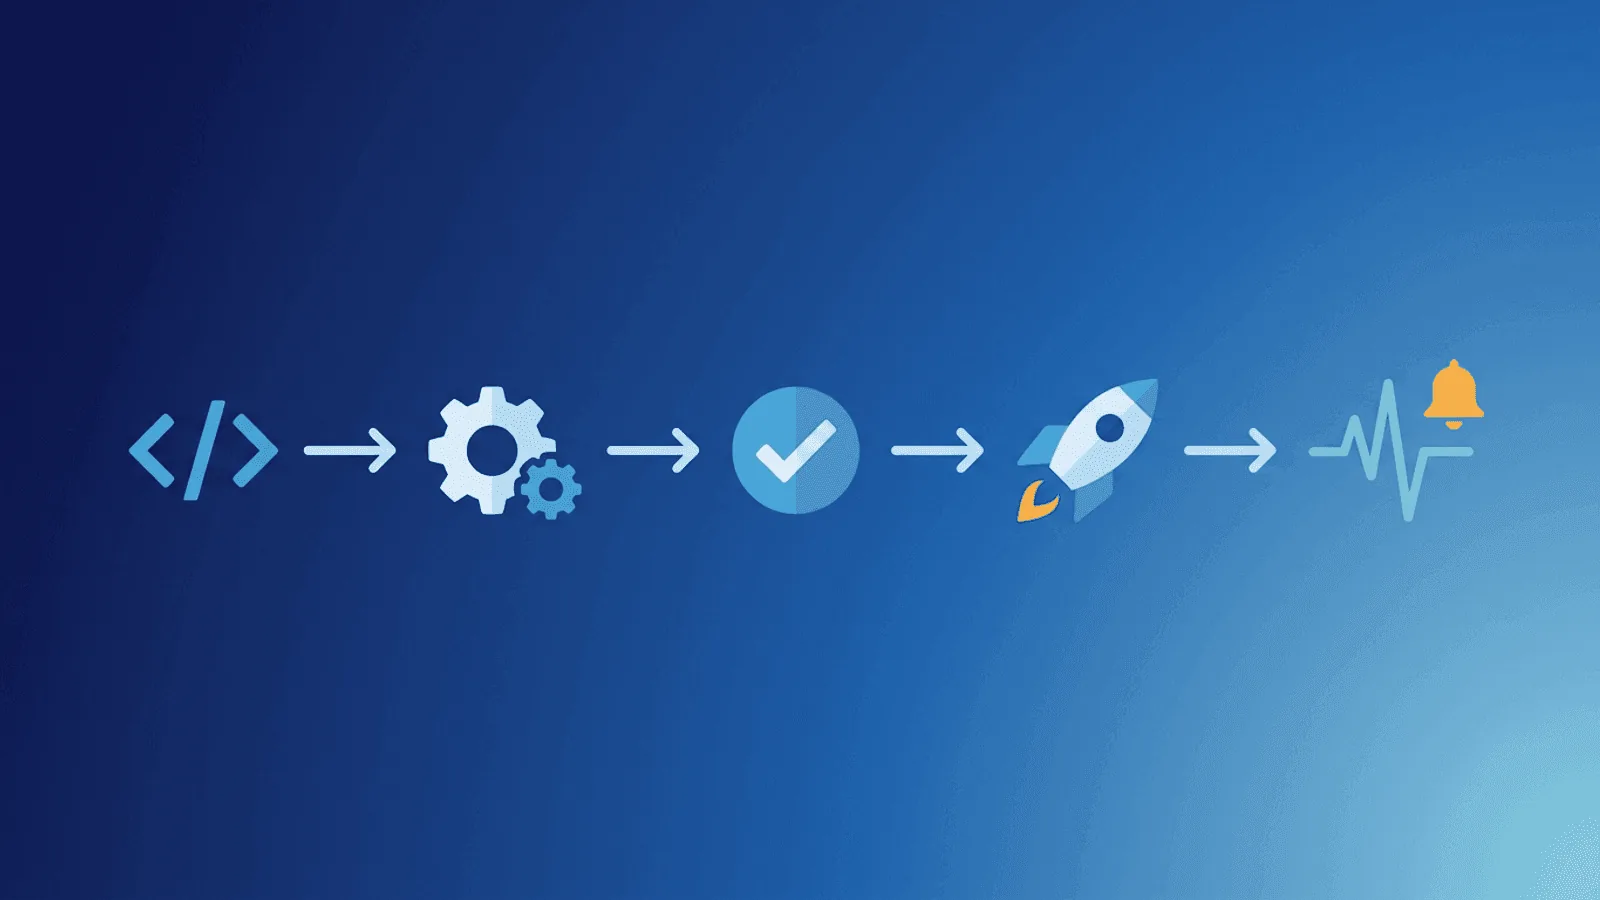
CI/CD Pipeline Monitoring: Builds, Deploys, Rollbacks
Monitor CI/CD builds and deployments with stage timing, queue health, rollout validation, rollback signals and alerts that catch false-success releases.
Docker Container Monitoring: Health Checks, Restarts & Uptime
Monitor Docker containers beyond HEALTHCHECK. Catch unhealthy restarts, OOMKilled events, crash loops, port failures, and HTTP errors with external checks.
Kubernetes Monitoring: Health Checks, Pod Uptime, and Alerting
Kubernetes clusters fail in ways that traditional monitoring misses. Learn how to monitor pod health, service endpoints, and set up alerts for K8s downtime.
Observability vs Monitoring: Differences and Examples
Monitoring detects defined conditions; observability supports investigation with telemetry. Learn their overlap, differences, and a practical adoption path.
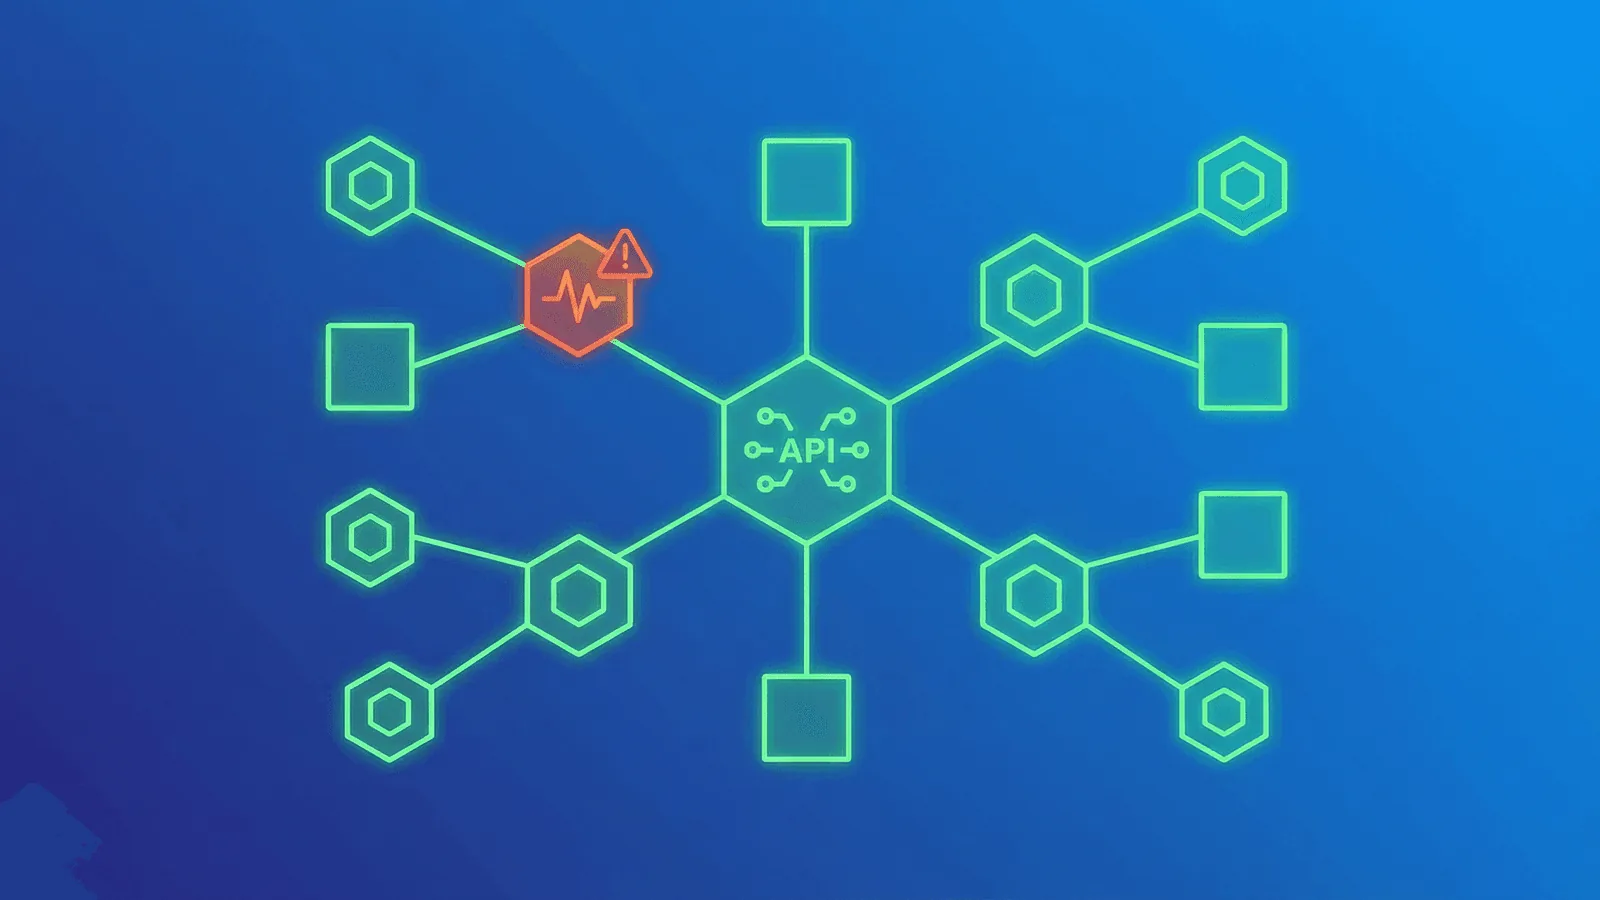
Microservices Monitoring: Health Checks, Dependencies, and Alerts
Build practical microservices monitoring for service health, dependencies, latency, queues, traces, and end-to-end user journeys with a staged rollout plan.
Incident Escalation Policy: Steps, Timeouts, and Ownership
Build an incident escalation policy with severity-based triggers, primary and backup ownership, acknowledgment timeouts, decision authority, and regular tests.
On-Call Schedule: Build a Fair, Covered Rotation
Set up an on-call rotation with coverage rules, primary and backup layers, handoffs, overrides, follow-the-sun shifts, escalation, and fairness metrics.
Cron Job Monitoring: Detect Failed, Late, and Missing Background Tasks
Monitor cron jobs and background tasks for missed schedules, failures, duration, retries, and bad output with heartbeats and result checks in production.
On-Call Without Burnout: A Sustainable Response System
Build sustainable on-call with explicit coverage, actionable pages, fair rotations, escalation, handoffs, recovery time, load metrics, and review loops.
Incident Postmortem Template: Blameless Review Guide
Use a concrete incident postmortem template covering impact, detection, timeline, contributing factors, recovery, lessons, and owned action items.