Memory Leaks in Production: Detection and Debugging Guide
Detect production memory leaks by separating heap, RSS, native memory, cache growth, and workload effects; capture profiles safely before OOM restarts.
Database Connection Pool Exhaustion: Diagnose and Fix It
Diagnose database connection pool exhaustion, distinguish client wait timeouts from server limits, size pools across replicas, and fix leaks safely.
Kubernetes CrashLoopBackOff: Causes and How to Fix It
What CrashLoopBackOff means, the common reasons a pod keeps restarting, and a step-by-step way to diagnose and fix the crash loop with kubectl.
Kubernetes ImagePullBackOff and ErrImagePull: How to Fix
What ImagePullBackOff and ErrImagePull mean, why Kubernetes can't pull your container image, and how to diagnose and fix the most common causes.
Kubernetes OOMKilled (Exit Code 137): Causes and Fixes
Why Kubernetes kills pods with OOMKilled and exit code 137, how memory requests and limits cause it, and how to diagnose and fix out-of-memory restarts.
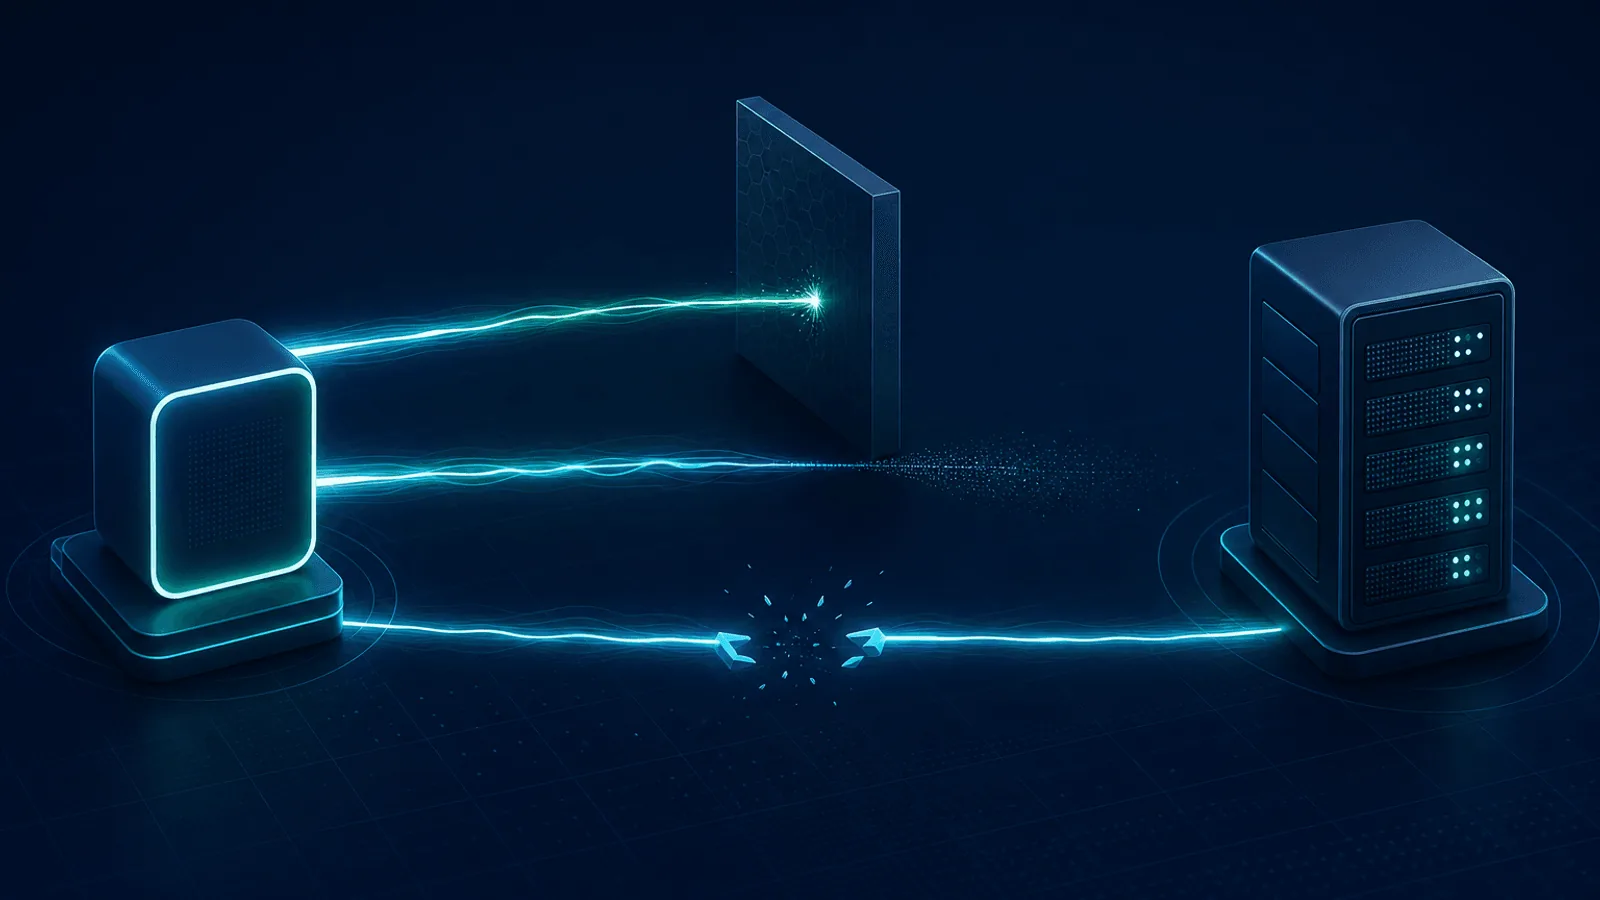
Connection Refused vs Connection Timed Out vs Reset (Fix Guide)
Fix connection refused (TCP RST), connection timed out, and connection reset errors. Step-by-step diagnostic checklist to test ports, firewalls, and servers.